Here are my thoughts on the free online textbook Is Parallel Programming Hard, And, If So, What Can You Do About It? by Paul E. McKenney, author of the Linux kernel’s RCU synchronization mechanism. I read a lot of this textbook, got my fill, and probably won’t read more of it in the near future so wanted to write this review while it is all still fresh.
Set & Setting
Here I’ll talk about the mindset/life phase and physical setting I was in when I started reading this textbook. This might be like the tedious personal flavor preamble they have on recipe websites so skip ahead if that does not interest you.
My professional life had revolved around TLA⁺ & distributed systems for the past decade, and I was thinking it was time for a change. A transitional and emotionally tumultuous period! In 2022 I had tried (and failed) to move to Lean, hoping to acquire an unbelievably niche & nonexistent job as the guy who formalizes researchers’ quantum information processing results for them. I burned out on that, which given recent advances in automated theorem proving might have been my temporarily-prescient nervous system dodging me a bullet. Thus was the history & context in which I attended the 2026 Software Should Work conference in Columbia, Missouri.
The conference had a lot of good talks, but I especially enjoyed the one on Fil-C by Filip Pizlo:
I also got to talk to Fil a fair bit, about interpreters and then about concurrency. I fancied myself pretty knowledgeable about concurrency from TLA⁺ & distributed systems, but Fil told me about the difficulty of writing a concurrent lock-free garbage collector and I realized I actually knew very little about concurrency (feeling that you know very little is the mark of a good conference). Fil also mentioned TLA⁺ might not be useful (or at least ergonomic) for reasoning about events which happen literally concurrently (an actual possibility with a multicore CPU!) and the importance of analyzing concurrent algorithms for linearizability, a concept I sort of understood in the distributed systems sense.
All of this seemed very alluring, so I looked around for a textbook to read about concurrency that focused more on lock-free aspects as opposed to mutex-based or message-passing patterns. Is Parallel Programming Hard, And, If So, What Can You Do About It? seemed to fit the bill, focusing as it does on general concurrent programming & CPU cache effects instead of more specific textbooks about how to write lock-free datastructures. It also had a few (2023, 2021, 2020, 2015, 2014, 2011) moderately interesting HN threads. I don’t think it’s useful spending time in analysis paralysis trying to find the exact “right” textbook (this is really just a clever way to procrastinate), so it seemed good enough.
The physical setting in which I read this textbook was a 1.5 week vacation to visit my family in a quiet, wooded part of Canada. 2026 also turned out to be a particularly horrific mosquito season. Thus I spent much of the time sitting in a cool screened-in patio, diligently watched over by hundreds of guards ensuring I did not leave my post:
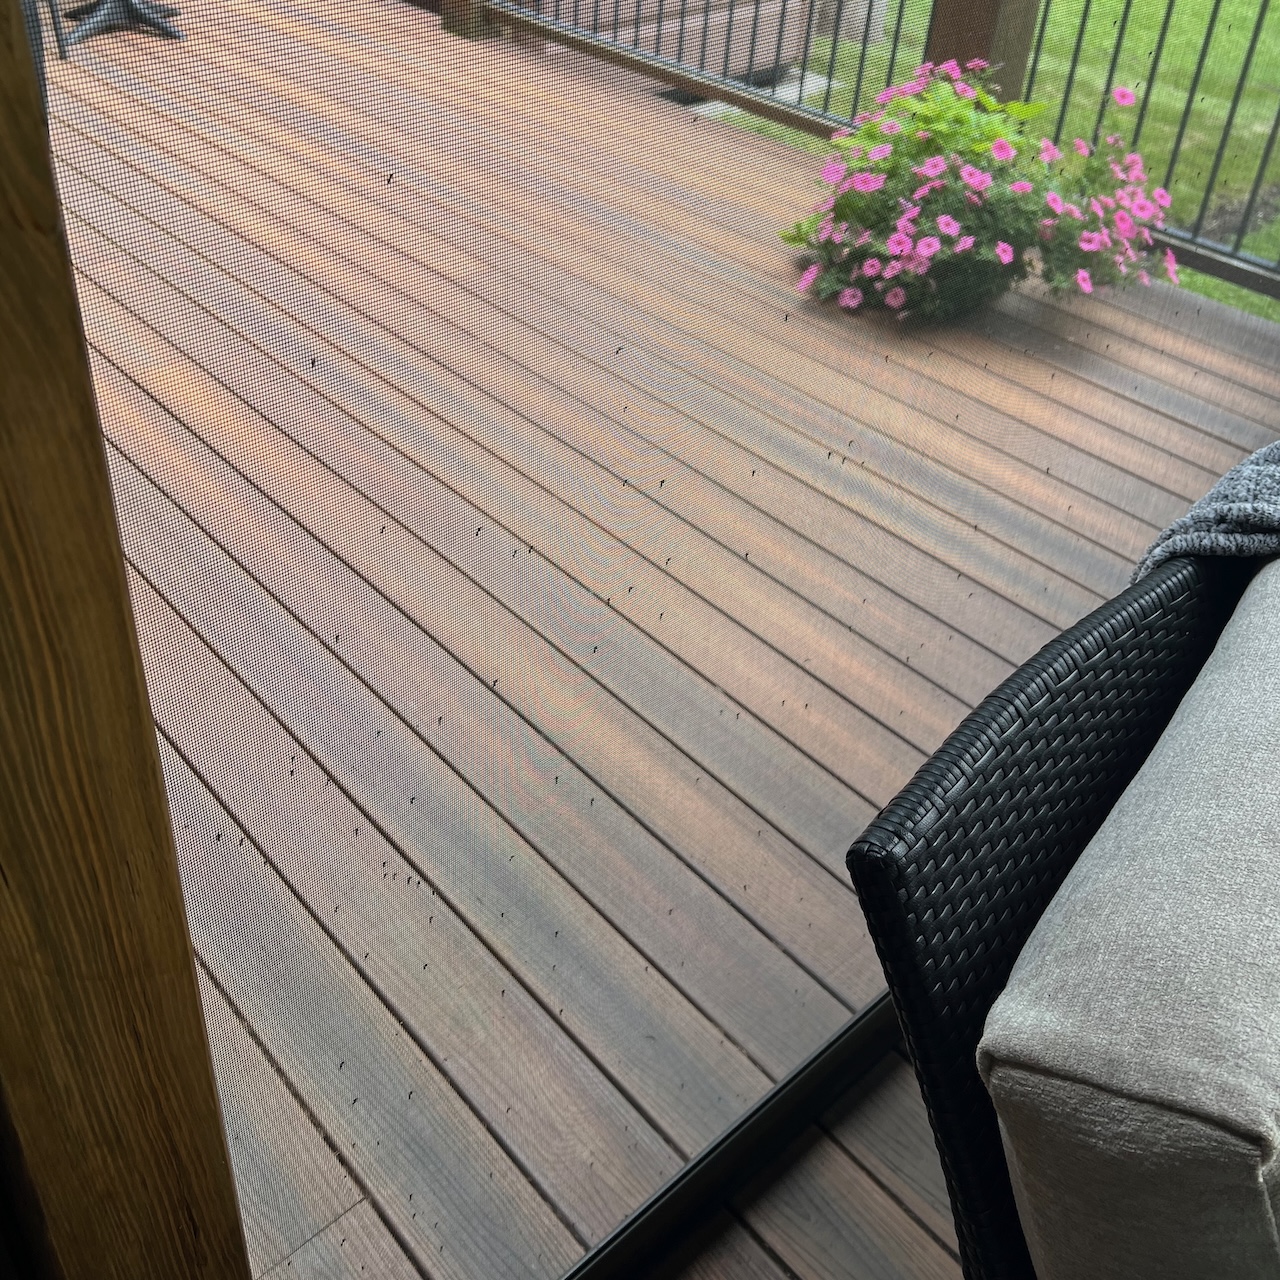
Satellites & cell towers have made distracting internet connectivity annoyingly good even in the more remote parts of the country, but otherwise this was an optimal textbook reading location.
The Textbook Format
Some quick notes on the actual structure of the textbook; it is available in no fewer than three separate formats, all PDF:
- A dual-column format, like a scientific paper
- A single-column format with large margins
- A single-column format with no margins
The last one is perfect for reading on my Pine64 PineNote.
The textbook contains a huge number of internal links. Some of these links are used in quick knowledge-check question boxes, where clicking the link takes you to the question’s answer. Other links are used whenever a figure or section is mentioned, or for copious footnotes & citations. Unfortunately the latter are very annoying and should probably be reduced by at least 80%. If your e-reader lacks physical page-turn buttons, then your experience of reading the book will consist of constantly accidentally pressing one of these links when you meant to turn the page and thus being sent who-knows-where. E-books are disorienting enough to navigate without this, and it pretty much meant it was impossible to quickly flip back & forth between two sections using repeated page-turn taps. For times where I did want to click a link, some places had two links right next to each other; touch screens lack the precision to reliably click one link instead of the other. The solution of simply disabling all links presents itself, but then you lose access to the quite nice knowledge-check questions. So I just suffered through it.
The Textbook Content - Introductory Chapters
The textbook was more or less the perfect presentation of material for my level. The book starts with nice light introduction & motivation chapters before heading off to the races in chapter 3, Hardware and its Habits. Here we learn about how modern CPUs work at a high level - what makes them fast, and what makes them slow. Complete with a bunch of humorous illustrations! Section 3.2.1 - Hardware System Architecture is where it really got interesting for me, as we are walked through a simplified account of a CPU core writing to a memory address that does not exist in its cache.
Here is one missed opportunity: I would have really benefited from a basic explanation of the MESI protocol, possessing essentially no intuition about how CPU caches mediate concurrent reads & writes. I found out about MESI while searching online to better understand this section; MESI is only mentioned in the appendix of this book. But my understanding of the rest of the book was greatly improved by knowing about it.
Learning about MESI also taught me that multiple CPU cores cannot write to the same data location literally concurrently! An x86 CPU doesn’t actually write directly to memory, it only writes to its cache (the cache value is then eventually flushed to memory). An x86 CPU core can only write to a particular address when it has exclusive ownership of the cacheline containing that address. If another core tries to write to that address at the same time, it has to wait for exclusive ownership of the cacheline to be moved to it. Thus literally concurrent writes do not actually happen. It is possible for writes to be torn if the data being written spans more than one cacheline, though.
Chapter 4, titled Tools of the Trade, was positively mind-bending. Here we learn that if you write parallel programs without due caution, the compiler will attempt unbelievably creative optimizations resulting in completely nonsensical behavior! Section 4.3.4.1, Shared-Variable Shenanigans, covers such horrifying mishaps as load tearing, store tearing, load fusing, store fusing, code reordering, invented loads, invented stores (particularly egregious), store-to-load transformations, and dead-code elimination. Then, assuming your code survived compilation unscathed, the chapter goes over the nonsense the CPU can pull when actually executing your program! This double trouble made it difficult for me to think straight about parallel programs beyond nice familiar mutexes or message-passing.
The one issue I had with this chapter is that it is very specific to a Linux kernel context.
I would have liked to have learned about the work C++11 and C11 did to formalize parallel programming with things like std::memory_order.
These were only given short paragraphs in sections 4.2.6 & 4.2.7, Atomic Operations (C11) and Atomic Operations (Modern GCC).
I escaped the chapter armed with a vague idea that the ACCESS_ONCE() and WRITE_ONCE() macros just cast things to volatile* and that was enough to scare away the compiler.
Very interesting historical developments, like the debate over whether benign data races were errors, were skipped entirely.
The Textbook Content - Main Chapters
Chapter 5, Counting, is probably the marquee chapter of the book. It was also the last chapter I read in any sort of depth. The chapter covers 10 or so different ways of writing a program where several threads increment a counter. The obvious non-broken implementation, where each thread uses atomic increment instructions, is dispatched early on by showing how terribly it performs. This is where my extracurricular understanding of MESI really came in helpful.
The chapter culminates in something called a signal-theft limit counter, which to be honest I do not entirely understand. I think if I were writing a counter myself I probably would not go that far. I really liked array-based per-thread statistical counters, with their similarity to conflict-free replicated datatypes from the distributed systems world. They were also an excellent vehicle for learning about the performance impact of false sharing - you can’t just chuck all the thread-specific counters in a single contiguous array and call it good!
After chapter 5 I mostly just skimmed the material looking for topics of interest. Some of the chapters were fairly conceptual, talking about ownership, partitioning, deferred processing, and other things readily translated from distributed systems. The Formal Verification chapter used Promela and Spin, which I wasn’t motivated to learn as a TLA⁺ user. The Validation chapter had a good section, 11.6.4, on Hunting Heisenbugs. Lock-free programming doesn’t really get covered until chapter 14, Advanced Synchronization, and at that point I was ready to move to a textbook focusing on lock-free programming & data structures specifically. Chapter 15 finally covers memory ordering, but I had already moved on to extracurricular sources trying to fix my confusion about it.
Overall review
Although I only read the first five chapters in-depth, I think this textbook is excellent.
I say this because it really gave me a thirst to learn more about parallel programming!
Most lunches at work I struggle to keep myself from infodumping whatever nonsense I’ve learned onto my coworkers.
Like did you know about the failure of formalizing release-consume ordering?
Or how basic aligned loads & stores using mov are atomic on x86?
Or out-of-thin-air values?
Or the incredibly weak memory model of the DEC Alpha?
Or how atomics on ARM (pre-v8) can be pre-empted?
There’s a goldmine of comedically unintuitive nonsense here.
I want to learn about high-performance garbage collection next.